Indexing API
We support Indexing API for grouping your documents in a custom manner in ArealAI. If your organization is using this feature, we will group your processed documents into your desired index format.
Example Views
Section titled “Example Views”Manage View
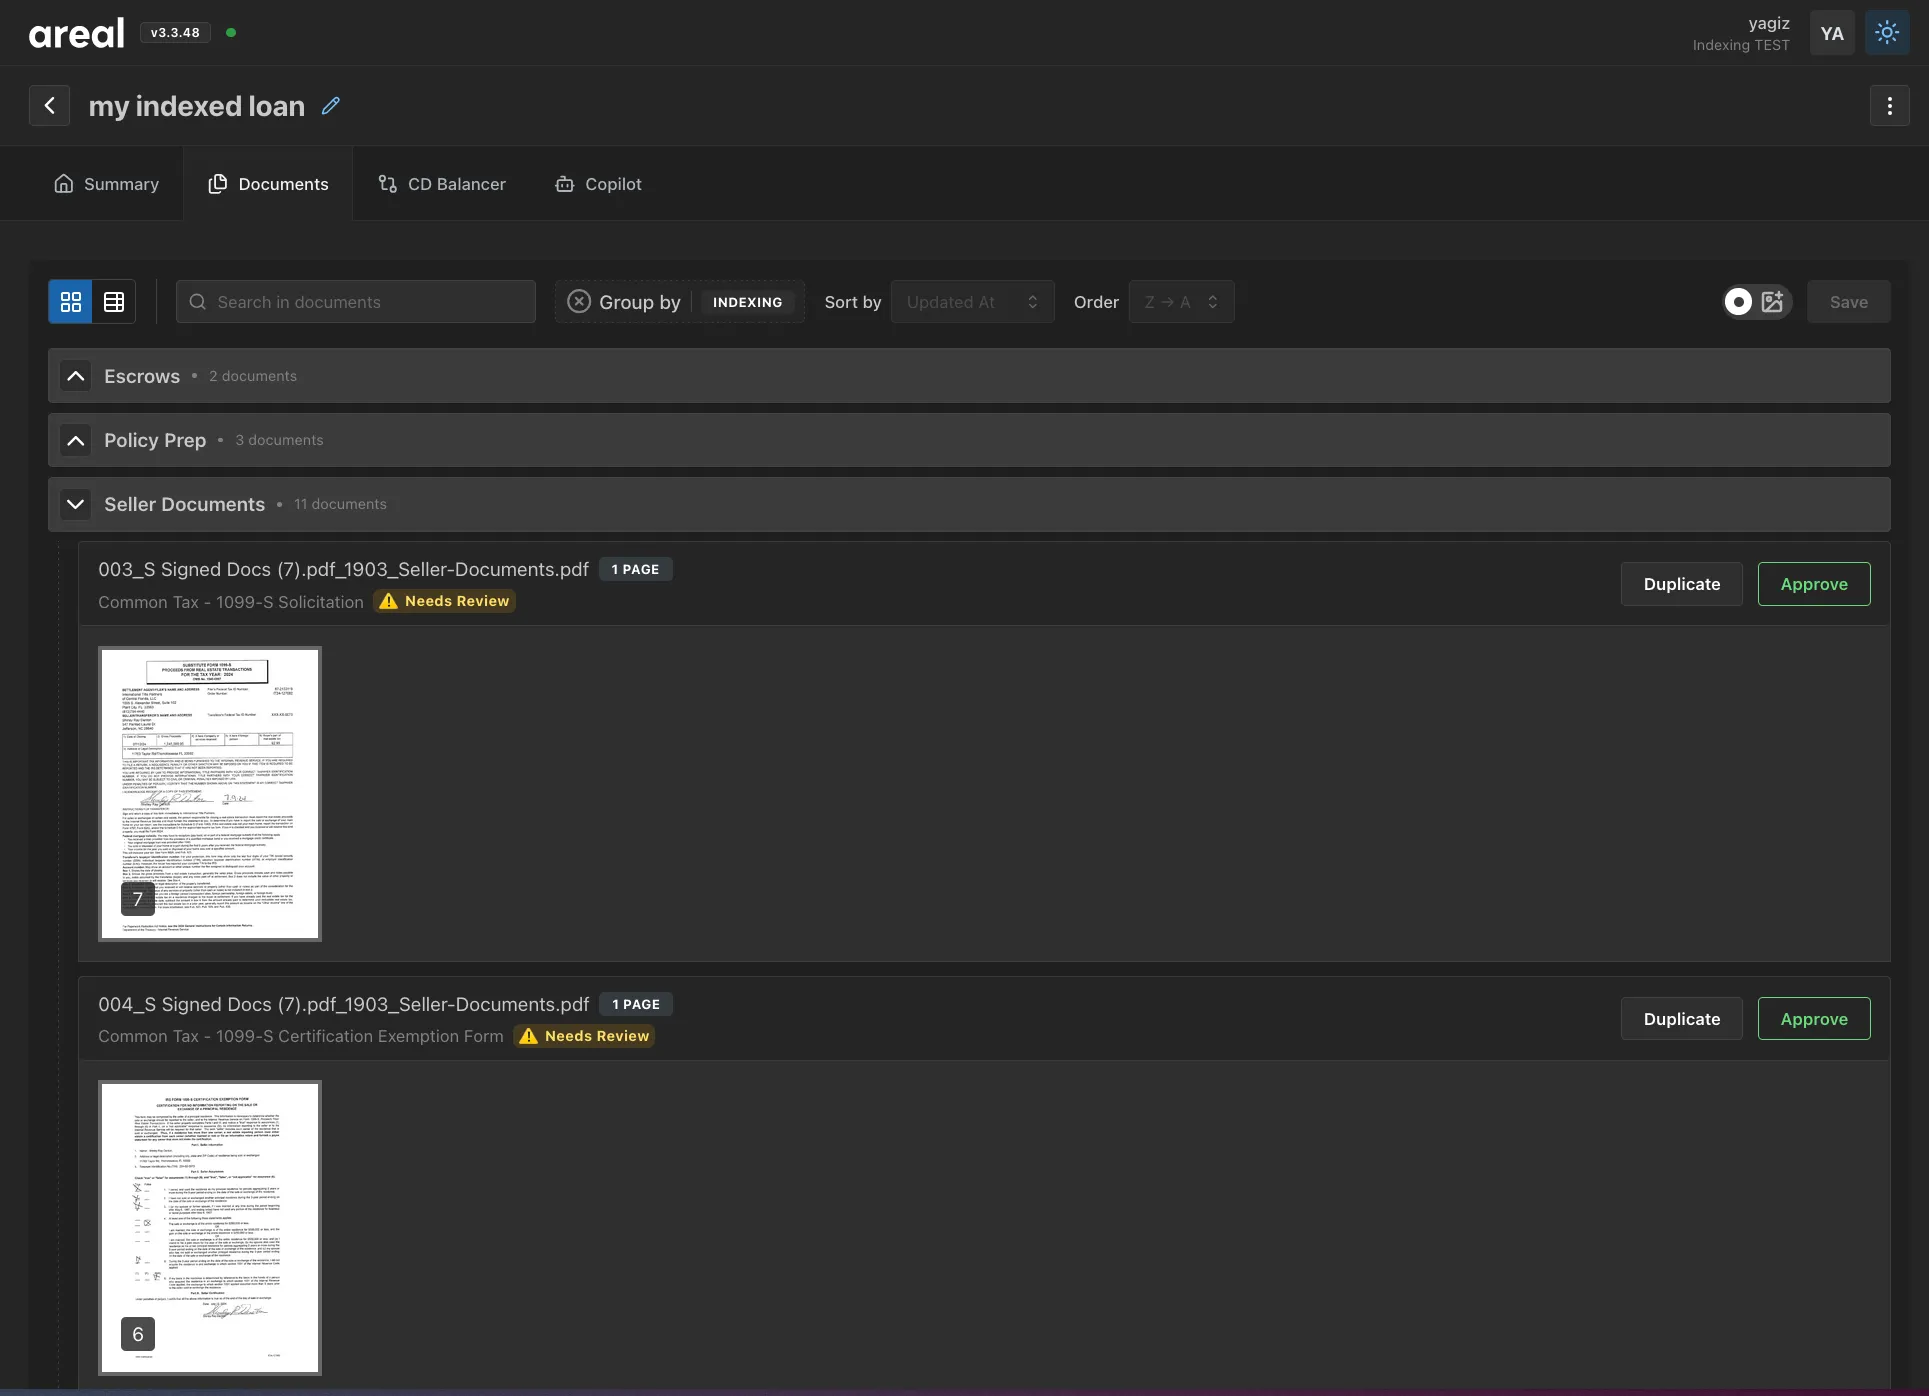
Section titled “Manage View”In ManageView you can move around the final documents within or across the indexes. You can also duplicate the documents for easier organization.
Document Duplicatation
Section titled “Document Duplicatation”When you click on the “Duplicate” button for each document, we will create a new document with the same content. We will add an indicator to reference the original document. And you will be able to move this newly created document to a new index
Downloading Indexed Documents
Section titled “Downloading Indexed Documents”Automatic Grouping
Section titled “Automatic Grouping”We provide an easy to use API to download the indexed documents in a zip file.
When group_by is set to index_id, we will put the documents in the same index into a folder.
import requests  # noqa
SESSION_ID = '66878f5e-c609-4796-9fc2-ecc6ae377cac'
response = client.post(    f'{BASE_URL}/sessions/{SESSION_ID}/download/', params={'group_by': 'index_id'})with open('documents.zip', 'wb') as f:    f.write(response.content)
print('✅ Zip file downloaded and saved as documents.zip')using System;using System.Net.Http;using System.Threading.Tasks;using System.IO;using System.Net;
var sessionId = "66878f5e-c609-4796-9fc2-ecc6ae377cac";var baseUrl = "http://dev-api.v2.areal.ai/api/v2";
// Assume client is already authenticatedvar handler = new HttpClientHandler{ UseCookies = true, CookieContainer = new CookieContainer()};var client = new HttpClient(handler);
var downloadUrl = $"{baseUrl}/sessions/{sessionId}/download/?group_by=index_id";var response = await client.PostAsync(downloadUrl, null);response.EnsureSuccessStatusCode();
var content = await response.Content.ReadAsByteArrayAsync();await File.WriteAllBytesAsync("documents.zip", content);
Console.WriteLine("✅ Zip file downloaded and saved as documents.zip");import java.net.HttpURLConnection;import java.net.URL;import java.io.FileOutputStream;import java.io.InputStream;import java.io.BufferedReader;import java.io.InputStreamReader;import java.net.CookieManager;import java.net.CookieHandler;import java.nio.charset.StandardCharsets;
public class AutomaticGrouping { public static void main(String[] args) throws Exception { String sessionId = "66878f5e-c609-4796-9fc2-ecc6ae377cac"; String baseUrl = "http://dev-api.v2.areal.ai/api/v2";
CookieManager cookieManager = new CookieManager(); CookieHandler.setDefault(cookieManager);
// Assume client is already authenticated String downloadUrl = baseUrl + "/sessions/" + sessionId + "/download/?group_by=index_id"; URL url = new URL(downloadUrl); HttpURLConnection connection = (HttpURLConnection) url.openConnection(); connection.setRequestMethod("POST"); connection.setDoInput(true);
int responseCode = connection.getResponseCode(); if (responseCode == HttpURLConnection.HTTP_OK) { try (InputStream inputStream = connection.getInputStream(); FileOutputStream outputStream = new FileOutputStream("documents.zip")) {
byte[] buffer = new byte[4096]; int bytesRead; while ((bytesRead = inputStream.read(buffer)) != -1) { outputStream.write(buffer, 0, bytesRead); } } System.out.println("✅ Zip file downloaded and saved as documents.zip"); }
connection.disconnect(); }}Manual Grouping
Section titled “Manual Grouping”You can easily download the indexed documents by filtering the documents by the index you want to download.
import requests  # noqa
SESSION_ID = '66878f5e-c609-4796-9fc2-ecc6ae377cac'
# if you don't know your index_ids, fetch them from the sessionresponse = client.get(    f'{BASE_URL}/sessions/{SESSION_ID}/',    params={'group_by': 'index_id'})response.raise_for_status()index_ids = list(set(o['index_id'] for o in response.json()['objects']))
# use them to filter documents by index_idindex_to_documents: dict[str, list[str]] = {}for index_id in index_ids:    response = client.get(        f'{BASE_URL}/sessions/{SESSION_ID}/',        params={'group_by': 'index_id', 'filter_by.index_id': index_id}    )    response.raise_for_status()    document_ids = [o['id'] for o in response.json()['objects']]    index_to_documents[index_id] = document_ids
# then download themfor index_id, document_ids in index_to_documents.items():    pdf_urls = []    for document_id in document_ids:        response = client.get(f'{BASE_URL}/documents/{document_id}/')        response.raise_for_status()        pdf_url = response.json()['pdf_url']
# actual download print(f'Downloading {pdf_url}...') response = requests.get(pdf_url) response.raise_for_status() print('File downloaded successfully')using System;using System.Net.Http;using System.Threading.Tasks;using System.Text.Json;using System.Net;using System.Collections.Generic;using System.Linq;
var sessionId = "66878f5e-c609-4796-9fc2-ecc6ae377cac";var baseUrl = "http://dev-api.v2.areal.ai/api/v2";
// Assume client is already authenticatedvar handler = new HttpClientHandler{ UseCookies = true, CookieContainer = new CookieContainer()};var client = new HttpClient(handler);
// if you don't know your index_ids, fetch them from the sessionvar sessionsUrl = $"{baseUrl}/sessions/{sessionId}/?group_by=index_id";var response = await client.GetAsync(sessionsUrl);response.EnsureSuccessStatusCode();
var content = await response.Content.ReadAsStringAsync();var jsonDoc = JsonDocument.Parse(content);var objects = jsonDoc.RootElement.GetProperty("objects").EnumerateArray();
var indexIds = new HashSet<string>();foreach (var obj in objects){ indexIds.Add(obj.GetProperty("index_id").GetString());}
// use them to filter documents by index_idvar indexToDocuments = new Dictionary<string, List<string>>();foreach (var indexId in indexIds){ var filterUrl = $"{baseUrl}/sessions/{sessionId}/?group_by=index_id&filter_by.index_id={indexId}"; var filterResponse = await client.GetAsync(filterUrl); filterResponse.EnsureSuccessStatusCode();
var filterContent = await filterResponse.Content.ReadAsStringAsync(); var filterJson = JsonDocument.Parse(filterContent); var filterObjects = filterJson.RootElement.GetProperty("objects").EnumerateArray();
var documentIds = new List<string>(); foreach (var obj in filterObjects) { documentIds.Add(obj.GetProperty("id").GetString()); } indexToDocuments[indexId] = documentIds;}
// then download themforeach (var (indexId, documentIds) in indexToDocuments){ foreach (var documentId in documentIds) { var documentUrl = $"{baseUrl}/documents/{documentId}/"; var docResponse = await client.GetAsync(documentUrl); docResponse.EnsureSuccessStatusCode();
var docContent = await docResponse.Content.ReadAsStringAsync(); var docJson = JsonDocument.Parse(docContent); var pdfUrl = docJson.RootElement.GetProperty("pdf_url").GetString();
// actual download Console.WriteLine($"Downloading {pdfUrl}..."); var pdfResponse = await client.GetAsync(pdfUrl); pdfResponse.EnsureSuccessStatusCode(); Console.WriteLine("File downloaded successfully"); }}import java.net.HttpURLConnection;import java.net.URL;import java.io.BufferedReader;import java.io.InputStreamReader;import java.net.CookieManager;import java.net.CookieHandler;import java.nio.charset.StandardCharsets;import java.util.*;import org.json.JSONObject;import org.json.JSONArray;
public class DownloadingIndexedDocuments { public static void main(String[] args) throws Exception { String sessionId = "66878f5e-c609-4796-9fc2-ecc6ae377cac"; String baseUrl = "http://dev-api.v2.areal.ai/api/v2";
CookieManager cookieManager = new CookieManager(); CookieHandler.setDefault(cookieManager);
// Assume client is already authenticated
// if you don't know your index_ids, fetch them from the session String sessionsUrl = baseUrl + "/sessions/" + sessionId + "/?group_by=index_id"; URL url = new URL(sessionsUrl); HttpURLConnection connection = (HttpURLConnection) url.openConnection(); connection.setRequestMethod("GET"); connection.setDoInput(true);
int responseCode = connection.getResponseCode(); if (responseCode == HttpURLConnection.HTTP_OK) { BufferedReader reader = new BufferedReader( new InputStreamReader(connection.getInputStream(), StandardCharsets.UTF_8) ); StringBuilder response = new StringBuilder(); String line; while ((line = reader.readLine()) != null) { response.append(line); } reader.close();
JSONObject jsonResponse = new JSONObject(response.toString()); JSONArray objects = jsonResponse.getJSONArray("objects");
Set<String> indexIds = new HashSet<>(); for (int i = 0; i < objects.length(); i++) { JSONObject obj = objects.getJSONObject(i); indexIds.add(obj.getString("index_id")); }
// use them to filter documents by index_id Map<String, List<String>> indexToDocuments = new HashMap<>(); for (String indexId : indexIds) { String filterUrl = baseUrl + "/sessions/" + sessionId + "/?group_by=index_id&filter_by.index_id=" + indexId; URL filterUrlObj = new URL(filterUrl); HttpURLConnection filterConnection = (HttpURLConnection) filterUrlObj.openConnection(); filterConnection.setRequestMethod("GET"); filterConnection.setDoInput(true);
int filterResponseCode = filterConnection.getResponseCode(); if (filterResponseCode == HttpURLConnection.HTTP_OK) { BufferedReader filterReader = new BufferedReader( new InputStreamReader(filterConnection.getInputStream(), StandardCharsets.UTF_8) ); StringBuilder filterResponse = new StringBuilder(); while ((line = filterReader.readLine()) != null) { filterResponse.append(line); } filterReader.close();
JSONObject filterJson = new JSONObject(filterResponse.toString()); JSONArray filterObjects = filterJson.getJSONArray("objects");
List<String> documentIds = new ArrayList<>(); for (int i = 0; i < filterObjects.length(); i++) { JSONObject obj = filterObjects.getJSONObject(i); documentIds.add(obj.getString("id")); } indexToDocuments.put(indexId, documentIds); } filterConnection.disconnect(); }
// then download them for (Map.Entry<String, List<String>> entry : indexToDocuments.entrySet()) { String indexId = entry.getKey(); List<String> documentIds = entry.getValue();
for (String documentId : documentIds) { String documentUrl = baseUrl + "/documents/" + documentId + "/"; URL docUrlObj = new URL(documentUrl); HttpURLConnection docConnection = (HttpURLConnection) docUrlObj.openConnection(); docConnection.setRequestMethod("GET"); docConnection.setDoInput(true);
int docResponseCode = docConnection.getResponseCode(); if (docResponseCode == HttpURLConnection.HTTP_OK) { BufferedReader docReader = new BufferedReader( new InputStreamReader(docConnection.getInputStream(), StandardCharsets.UTF_8) ); StringBuilder docResponse = new StringBuilder(); while ((line = docReader.readLine()) != null) { docResponse.append(line); } docReader.close();
JSONObject docJson = new JSONObject(docResponse.toString()); String pdfUrl = docJson.getString("pdf_url");
// actual download System.out.println("Downloading " + pdfUrl + "..."); URL pdfUrlObj = new URL(pdfUrl); HttpURLConnection pdfConnection = (HttpURLConnection) pdfUrlObj.openConnection(); pdfConnection.setRequestMethod("GET"); pdfConnection.setDoInput(true);
int pdfResponseCode = pdfConnection.getResponseCode(); if (pdfResponseCode == HttpURLConnection.HTTP_OK) { // File download logic here - save to appropriate location System.out.println("File downloaded successfully"); } pdfConnection.disconnect(); } docConnection.disconnect(); } } }
connection.disconnect(); }}